What OCR actually means
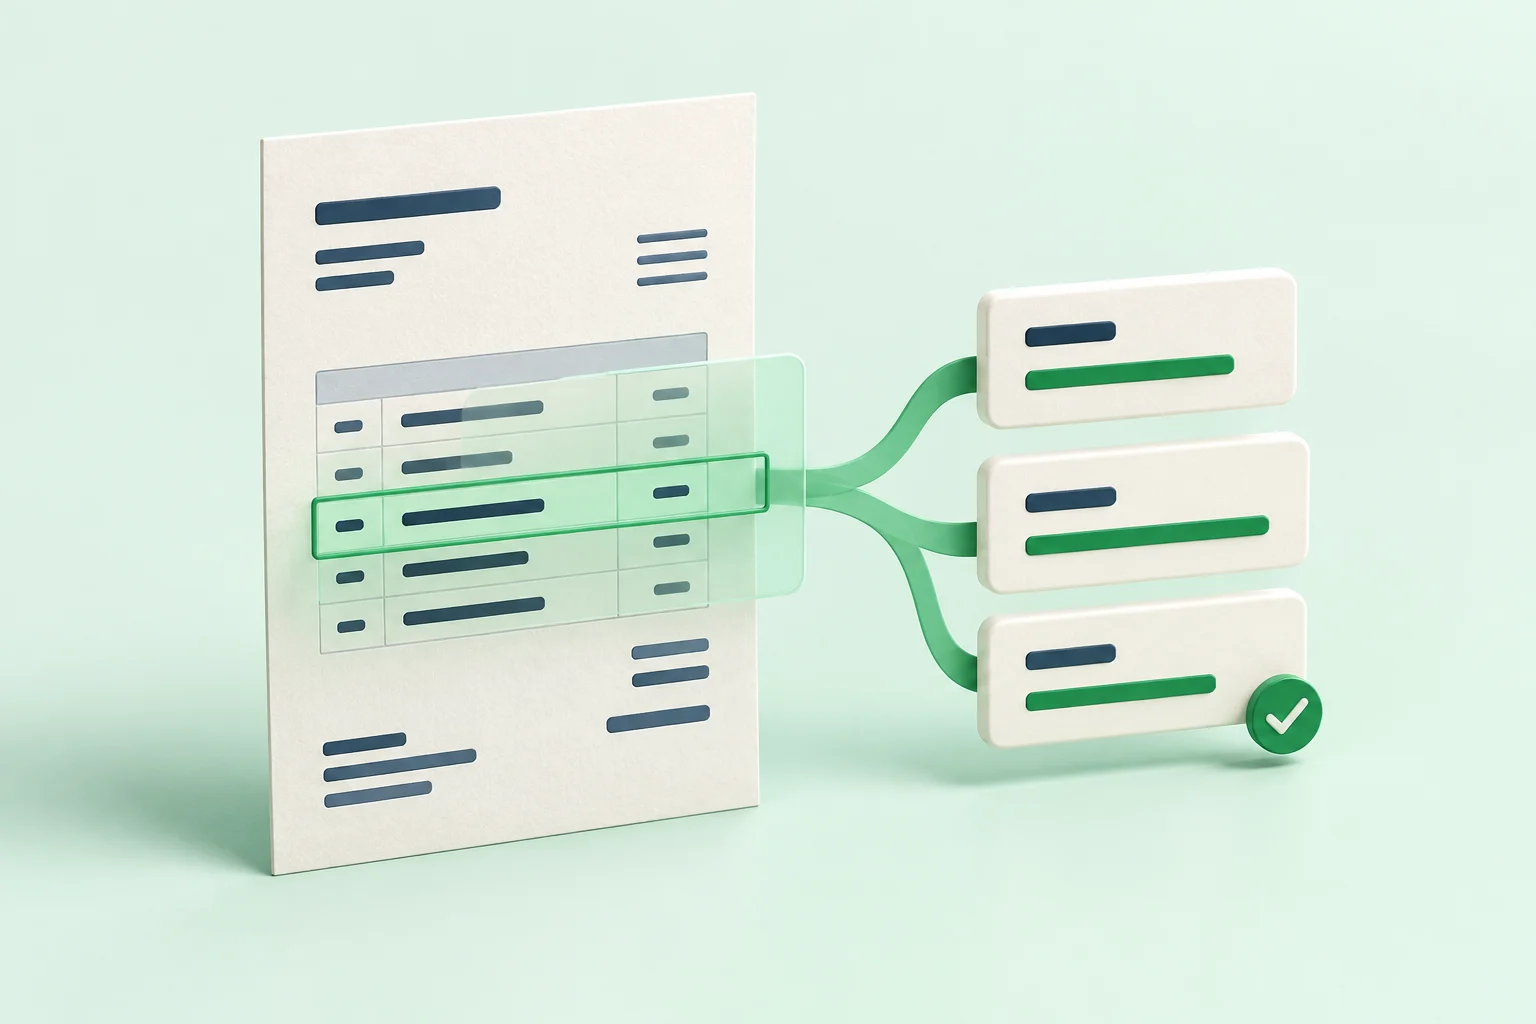
OCR stands for optical character recognition: software that recognises text in a document image. Think of it as a way to avoid starting every form with an empty box. A system may then use other processing to organise that text into useful fields.
A supplier name, date, and total can look very different across documents. Reading the characters is only part of the job. Placing each value in the intended field is another part.
OCR reads text. Your review decides whether the resulting record is ready.
Read the source beside the fields
When trying an extraction workflow, keep the original document next to the prepared values. Follow the same review order every time: supplier, reference, dates, amounts, and any additional details your process requires.
Watch for a due date placed in an invoice-date field or a subtotal mistaken for the final amount. Compare the labels on the document, not only the numbers. Treat unclear information as a question to resolve rather than something to guess.
Start small and check the exceptions
Test a clear invoice, a receipt photo, and a more complicated document from your normal workload. Notice which fields need attention. That gives you a practical review checklist for your own documents.
The useful question is not “Can it read every page perfectly?” It is “Can I quickly see what it read, correct what needs attention, and approve with confidence?” Keep that distinction visible as you build your process.
This is a sample editorial guide.